---
title: "Introducing GoePT-1-20M"
language: en
locale: al
date: 2026-09-11
canonical: https://alman.ai/al/blog/introducing-goept-1-20m/
---
*I used AI tools to draft this post from the experiment records, then reviewed and edited the result. The prose reads as AI-written in places, and I am aware of it.*
[GoePT-1-20M](https://huggingface.co/osolmaz/GoePT-1-20M) is a 20-million-parameter model for translating Standard German into [Alman](/), a simplified German dialect. Alman keeps German vocabulary and much of its sentence structure while removing grammatical gender and most case inflection. The model runs entirely in the browser, keeps the text on the reader's device, and needs no GPU or model API.
The intended use is a reading aid for people learning German as an additional language. [Almanpedia](https://almanpedia.org), the main application, uses GoePT to translate German Wikipedia and lets readers compare the result with the original. You can also try the model on your own text in the [online translator](https://alman.ai/translate/).
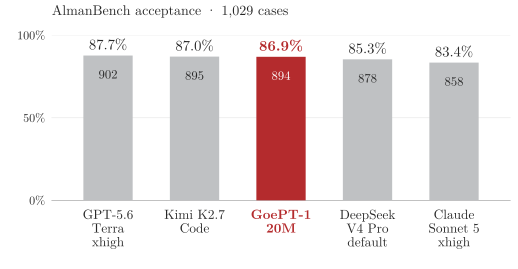
GoePT scored **86.9% on [AlmanBench](/almanbench/)**, a benchmark that checks translations against Alman's rules. This puts it just above DeepSeek-V4-Pro's **85.3%**, with about **80 thousand times fewer parameters**.
The training work ran on Hugging Face infrastructure, using ten million teacher-generated sentence pairs mixed with reviewed translations. Through [ML Claw](https://github.com/huggingface/mlclaw), an OpenClaw deployment on Hugging Face, the author directed the training run from a phone using Telegram.
The goal of this side project was to show that you can *vibe* machine learning now, including dataset creation, autoresearch, and the final training run. Hat tip to [ML Intern](https://github.com/huggingface/ml-intern), which inspired ML Claw and is now available in [Hugging Chat](https://huggingface.co/chat/).
## Alman and Almanpedia
The [Alman specification](/#spec) gives speakers and translation models a consistent set of rules to apply. Some of these rules formalize shortcuts I use myself as a non-native German speaker, as described in [the first Alman announcement](/blog/out-of-stealth/).
A learner can read familiar subject matter with fewer inflected forms to resolve, then compare it with the German original.
[Economic Burden of Language Complexity](/blog/economic-burden-of-language-complexity/) discussed how the time adults spend learning a language affects their work and participation in society. The [article-frequency study](/blog/frequencies-german-definite-articles/) examined how German articles occur in written and spoken material. These posts explain the motivation for the project. Alman is also a linguistic hobby, with a specification and regression checks.
### Reading Wikipedia
[Almanpedia](https://almanpedia.org) is the main application. It loads articles from German Wikipedia and translates their prose locally with GoePT-1-20M. Readers can switch between the original and the Alman rendering, or inspect the changes. The article's links and citations remain usable.
Replace `de.wikipedia.org` with `almanpedia.org` in an article's address, or search from the Almanpedia homepage. For example, [the article on the German language](https://almanpedia.org/wiki/Deutsche_Sprache) is a suitable place to begin.
The browser downloads the model once and keeps it in its model cache. Loading Wikipedia articles and downloading the model require network access, but translation requests stay on the reader's device. The application keeps the original German available when a block cannot be translated safely.
Reading full articles exposes errors that short benchmark sentences can miss, including awkward sentence boundaries and changes around links. Almanpedia makes it easy to compare the model's output with the text it was meant to preserve.
## Results
We measured translation quality and browser performance separately. AlmanBench checks whether an output matches a rendering licensed by the specification. Two additional eval sets use exact matches to their reference translations.
### AlmanBench
GoePT passed **894 of 1,029 cases**. DeepSeek-V4-Pro, the closest lower-scoring model on the [leaderboard](/almanbench/), passed **878**. The difference is **16 cases, or 1.6 percentage points**. The [recorded DeepSeek run](https://huggingface.co/datasets/osolmaz/almanbench-results) used Novita with default reasoning settings. Figure 1 places GoePT among the nearest scores on either side, using the same source sentences and acceptance sets.
[](/assets/images/introducing-goept-1-20m/adjacent-model-scores.svg "Open figure 1 at full size")
Figure 1. The two nearest scores above and below GoePT on the same 1,029 AlmanBench cases. Red marks GoePT, and the counts inside each bar show accepted cases. These are single-run results.
[DeepSeek reports](https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro) 1.6 trillion total parameters, about 80,000 times GoePT's 19.94 million. Its mixture-of-experts architecture activates 49 billion per token, still about 2,460 times GoePT's total.
The score difference is small. GoePT passed 95 cases that DeepSeek missed, while DeepSeek passed 79 that GoePT missed. We treat this as a practical tie from one run per model. GoePT reaches that score in a browser-sized model trained specifically for this task.
GoePT also scored above Claude Sonnet 5 at **858/1,029 (83.4%)** and Qwen3.8-27B at **857/1,029 (83.3%)**. Their recorded runs used xhigh and medium reasoning, respectively.
### Browser performance
The browser release uses int8 ONNX weights and single-threaded ONNX Runtime WebAssembly. The complete package is **58.14 MB**, including the runtime, with about **33 MB** of model weights. In the recorded Chromium check, a 2,018-word page completed in **6.43 seconds**. That is a measurement of one fixed page, not a speed promise for every reader's device.
We checked the browser export against the native model on all three eval sets.
| Eval | Native | Browser int8 |
| --- | --- | --- |
| AlmanBench acceptance | 894/1,029 · 86.88% | 894/1,029 · 86.88% |
| 3,512-row eval, exact match | 2,829/3,512 · 80.55% | 2,819/3,512 · 80.27% |
| 3,204-row held-out eval, exact match | 2,538/3,204 · 79.21% | 2,540/3,204 · 79.28% |
Quantization changed some outputs. It cost ten exact matches on the 3,512-row eval and gained two on the 3,204-row eval. That does not establish a quality advantage for either runtime. Native and browser inference accepted the same 894 AlmanBench cases.
### Translation quality
In informal use, most of GoePT's translations look correct. The most noticeable weakness is overcorrection around proper names and foreign words. GoePT also shows a strong preference for *von die* where retaining *der* would preserve the original construction and read more naturally.
One example comes from GoePT's translation of the [Odysseus article](https://almanpedia.org/wiki/Odysseus). The [German original](https://de.wikipedia.org/wiki/Odysseus) reads:
Er war der Sohn des Laërtes (in weniger verbreiteten Versionen des Sisyphos) und der Antikleia sowie der Bruder der Ktimene.
GoePT produced:
Er war die Sohn von die Laërt (in weniger verbreitete Versionen von die Sisyphos) und die Antikleia sowie die Bruder von die Ktimene
*Laërtes* becomes *Laërt*, removing part of the name. The final *-es* belongs to the name and should remain. The repeated *von die* is a separate issue. Both genitive constructions are allowed by the [specification](/#spec), which prefers retaining *der* when translating an existing genitive. Here, forms such as *die Sohn der Laërtes* and *die Bruder der Ktimene* would preserve that construction.
The working hypothesis is that the synthetic training pairs overrepresent *von die* and teach the student to remove endings too freely. This still needs a corpus audit. A goal for the next iteration is to correct that distribution and add targeted checks for proper names and foreign words, so that simplification removes grammatical endings without damaging the words themselves.
## Training on Hugging Face
The author directed the training run from a phone through Telegram, using [ML Claw](https://github.com/huggingface/mlclaw), an OpenClaw deployment on Hugging Face. The GPU work ran as Hugging Face Jobs, with datasets and checkpoints kept in Hub repositories and Storage Buckets.
I ran into problems pausing and resuming jobs and making sure runs finished with their outputs saved. I built [hf-job-control](https://github.com/osolmaz/hf-job-control) to control the training jobs better. The library lets workers save their state at safe checkpoints, resume from saved progress, and finish a run cleanly.
Reported durations are active Hugging Face job time, including setup, evals, and checkpoint uploads.
The training method was sequence-level distillation. A larger **teacher** produced translations, and a smaller **student** learned to reproduce them. The student became the model shipped to readers.
### Reference data
We began with 66,000 German–Alman sentence pairs. Sources include literature and everyday sentences, with modern material from Wikipedia and other openly licensed collections. There are also informal and rule-targeted examples. The translations were drafted with LLM assistance and reviewed in three passes against the Alman specification.
We reserved separate eval sets of 3,512 and 3,204 rows and excluded 262 training rows that overlapped AlmanBench. That left 59,022 reviewed training pairs. The teacher used all of them. The student used 56,069, with the remaining 2,953 reserved for checkpoint selection.
### Autoresearch experiments
The final recipe followed a series of autoresearch experiments. The agent proposed changes, ran small checks, trained candidates, and compared their outputs. The work covered tokenizer design, decoder depth, training mixtures, and data scale. Each comparison used fixed eval cases and scoring rules. Experiment journals record the hypotheses and settings alongside results and reasons for keeping or rejecting candidates. Saved run reports identify the exact inputs and model artifacts.
An early scaling series kept the 20-million-parameter student fixed and increased the number of unique generated pairs. It used an earlier teacher and data snapshot, before the final ByT5-Base work. All three runs used the same 2,953 checkpoint-selection cases. AlmanBench stayed out of these choices.
| Generated training pairs | Exact matches out of 2,953 |
| --- | ---: |
| 250,000 | 1,774 |
| 500,000 | 1,889 |
| 980,000 | 1,937 |
More data improved the score, with smaller gains at the upper end. A larger, 25.8-million-parameter student reached 2,014 matches, another 77 cases. Its complete browser package occupied 66.05 MB, and the fixed page took 7.71 seconds. Both exceeded the 60 MB and seven-second limits, so the larger student was not used for release.
A later 250,000-pair pilot used the final ByT5-Base teacher to compare greedy decoding with beam search of width four. Students trained on these targets reached 2,048 and 2,060 exact matches out of 2,953, respectively. The twelve-case gain was only 0.4 percentage points, with one student run per method. The slowest beam-search worker took 87 minutes, compared with 62 for greedy decoding. After reviewing that cost and the uncertain quality gain, we kept greedy decoding for the full corpus.
### Teacher and generated pairs
We fine-tuned ByT5-Base, a 582-million-parameter model, for six epochs on about 60,000 reviewed sentence pairs to produce the teacher.
Training took **2 hours 34 minutes** on one **NVIDIA H200 with 141 GB of GPU memory**. We used AdamW with a batch size of eight and a peak learning rate of 0.0001. Weights and optimizer state stayed in FP32, with BF16 computation.
The teacher translated 9,999,555 German sentences from `coral-nlp/german-commons`. The source mix covers Wikipedia and discussion pages, newspaper comments, legal documents, public tenders, news, and political speeches. Overlaps with the protected eval sources were removed before generation.
Eight H200 workers generated the translations with greedy decoding and a batch size of 1,024. They saved 204 output chunks to Hugging Face Storage Buckets. A merge checked row ordering and source alignment as well as the checksums. Generation produced about 6.47 GB of paired text. From the first worker's start to the last worker's finish, it took **2 hours 32 minutes**. The eight workers used **19.54 H200-hours** in total. A 20,000-row synthetic holdout left 9,979,555 generated pairs for training.
### Student
GoePT-1-20M is a Marian encoder–decoder trained from random weights. It has six encoder layers and one decoder layer, model width 384, eight attention heads, and feed-forward width 1,536. The 16,000-token SentencePiece tokenizer includes byte fallback. The model supports source and target sequences up to 1,024 tokens.
The training stream alternated one generated pair with one reviewed pair. This gave both sources equal weight even though the generated corpus was much larger. The 56,069 reviewed pairs repeated throughout the run.
| Training setting | Value |
| --- | --- |
| Hardware | One NVIDIA H200, 141 GB GPU memory |
| Optimizer | AdamW |
| Peak learning rate | 0.0003 |
| Batch size | 256 |
| Weight decay | 0.01 |
| Label smoothing | 0.1 |
| Dropout | 0.1 |
| Gradient norm limit | 1.0 |
| Schedule | 5% linear warmup, then cosine decay |
| Precision | FP32 weights and optimizer state, BF16 computation |
The agent proposed this architecture and these hyperparameters through the autoresearch work, with some settings carried over from earlier runs. A more experienced ML engineer may spot poor choices that I did not know to question. There is probably still room to improve the recipe, which I consider future work.
The full two-pass student training run used **5 hours 23 minutes of H200 job time**.
### Checkpoint selection
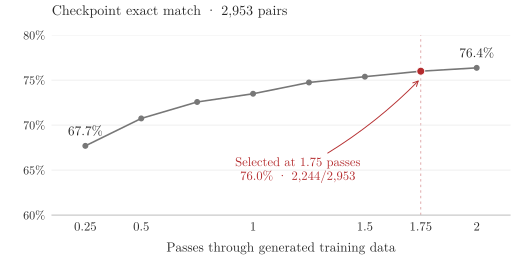
The run completed two passes through the generated training data. With the repeated reference pairs, that amounted to 39,918,220 example presentations. We saved checkpoints and checked the 2,953 selection cases after every quarter pass.
The selected checkpoint was step 136,444, after 1.75 passes and 34,928,442 presentations. The final checkpoint gained eleven exact matches on the selection set, below the fifteen-case threshold for choosing a later checkpoint, so we kept the earlier one.
[](/assets/images/introducing-goept-1-20m/checkpoint-selection.svg "Open figure 2 at full size")
Figure 2. Exact match on 2,953 checkpoint-selection pairs, measured every quarter pass. Red marks the selected checkpoint. The final checkpoint added eleven matches, below the fifteen-case threshold for replacing it.
The teacher had seen the student's checkpoint-selection pairs. Both separate eval sets stayed out of teacher and student training. The 3,204-row held-out eval was used only after the browser model was selected.
### Cost
At Hugging Face's [published rate of USD 5 per H200-hour](https://huggingface.co/docs/hub/jobs-pricing#gpu), the teacher fine-tune, target generation, and student training reported above amount to **about USD 137**. They used **27.50 H200-hours** in total.
This is a list-price estimate from recorded job time. It excludes the earlier experiments, separate preparation and export jobs, storage, and agent and LLM API costs. It is not the total project cost or a provider invoice.
German-to-Alman translation is a toy problem with unusually explicit rules. Hugging Face supplied the GPU jobs and durable storage. [ML Claw](https://github.com/huggingface/mlclaw) made those tools accessible through conversation, while the specification gave the work a result that could be checked.
The same setup can support other small ML applications with clear requirements. Here it produced a local reading tool for people learning German.
## Availability
Open [Almanpedia](https://almanpedia.org) to read an article, or paste a sentence into the [translator](https://alman.ai/translate/). The [GoePT-1-20M repository](https://huggingface.co/osolmaz/GoePT-1-20M) contains the browser package. Its [release manifest](https://huggingface.co/osolmaz/GoePT-1-20M/blob/main/browser.json) records the file checksums and browser checks.
If a translation looks wrong, compare it with the [Alman specification](/#spec) and [send an example](https://github.com/osolmaz/alman/issues). A short source sentence and the model's output are enough to begin.